How to Scrape Reddit Data in 2026
Reddit shut most of the old scraping routes between late 2025 and mid-2026. We tested what’s left and show the legal ways to get posts and comments now, with PRAW code, costs and the deadlines that matter.
If you copied a Reddit scraper from an old tutorial, it’s probably failing right now.
We tried the classic trick on October 9, 2026: add .json to a subreddit URL and read the data. Reddit answered with a 403 and a page reading “You’ve been blocked by network security.” Old Reddit sent us straight to a login screen.
That isn’t a bug in your code. Between late 2025 and mid-2026, Reddit closed self-serve API keys, logged-out JSON and logged-out Old Reddit, one door at a time. Two more close within months.
You can still scrape Reddit data in 2026 without fighting its defenses, if you pick the route that fits who you are. Here’s each one, with working code, real costs and the deadlines you can’t afford to miss.
- Logged-out .json, logged-out Old Reddit and self-serve API keys stopped working between late 2025 and mid-2026.
- The official API still works for approved apps, but new requests close on October 31, 2026, and public access ends in March 2027.
- Academics get a free, official route. Businesses need a contract or a data vendor.
- Routing around Reddit’s blocks with proxies is now the riskiest option, technically and legally.
Why Your Reddit Scraper Stopped Working
Reddit didn’t flip one switch. It closed the open routes over three years, and most tutorials still teach the ones that are gone.
| When | What changed | What it broke |
|---|---|---|
| July 2023 | Paid tier for heavy Data API use, at $0.24 per 1,000 calls | Third-party apps such as Apollo |
| July 2024 | robots.txt started blocking every crawler | Search engines and archive bots without a deal |
| Late 2025 | Responsible Builder Policy: every app needs approval | Instant API keys from the app settings page |
| May 2026 | Logged-out .json endpoints shut down | The “add .json to any URL” trick |
| Summer 2026 | Old Reddit requires a login | Simple HTML scrapers |
| November 13, 2026 | RSS feeds end | Feed readers and RSS-based monitors |
| January 12, 2027 | Unregistered apps lose API access | Bots and scripts that never registered |
| March 2027 | The public Data API closes | Free, non-commercial API access |
The reason is money as much as abuse. Reddit licenses its data to Google, reportedly for about $60M a year, and to OpenAI. Its “other revenue,” which includes that licensing, grew 24% year over year to $43.3M in the second quarter of 2026. Free bulk access undercuts those deals.
Reddit’s September 30, 2026 announcements set the rest of the timeline. It stops taking new public API requests on October 31, starts cutting off unregistered apps on January 12, 2027, and closes the public API in March 2027, as TechCrunch and The Next Web reported.
We Tested the Old Tricks
Before writing this guide, we checked the routes older tutorials still recommend. We sent four requests on October 9, 2026, from a residential connection, with an honest, descriptive User-Agent:
www.reddit.com/r/webscraping/top.jsonwith curl: HTTP 403 and a 190 KB block page.The same path on
old.reddit.com: a 302 redirect to the login page.The JSON URL in headless Chrome: the same block page.
The normal subreddit page in headless Chrome: blocked as well.
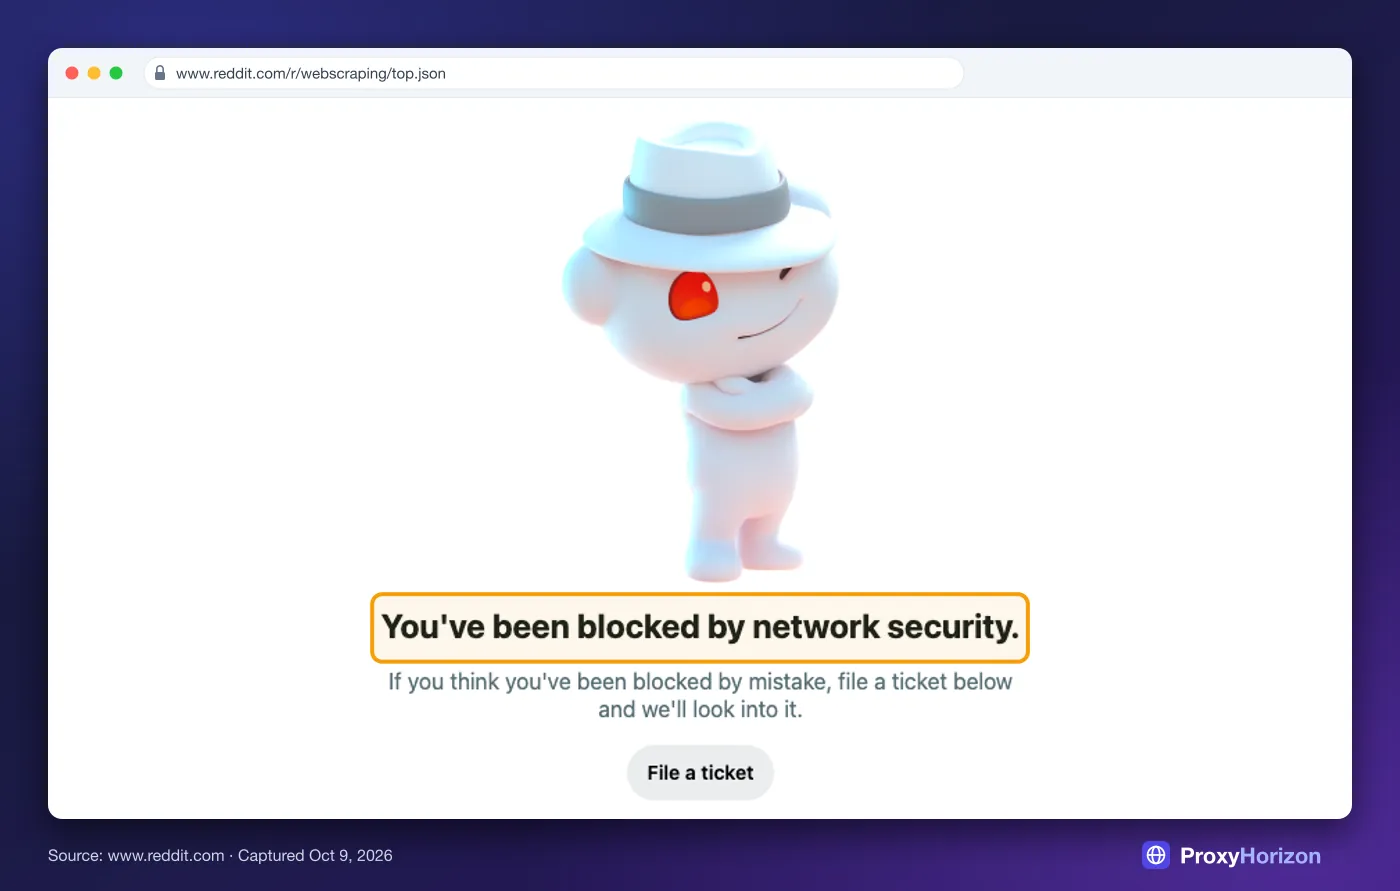
Headless browsers are easy to spot, as our guide to how anti-bot systems detect automated browsers explains. So we stopped there. Retrying a block from fresh IPs is exactly what Reddit’s rules forbid, and it’s the habit that drags projects into legal trouble.
Reddit’s robots.txt, fetched the same day, says the same thing in two lines:
User-agent: *
Disallow: /
Reddit’s API wiki says robots.txt is “for search engines, not Data API users.” For a scraper, though, the message is plain: no crawling without a deal.
The Routes That Still Work in 2026
Five routes are left. Two are fully official, two sit in a gray zone, and the main one stops taking new applicants on October 31, 2026.
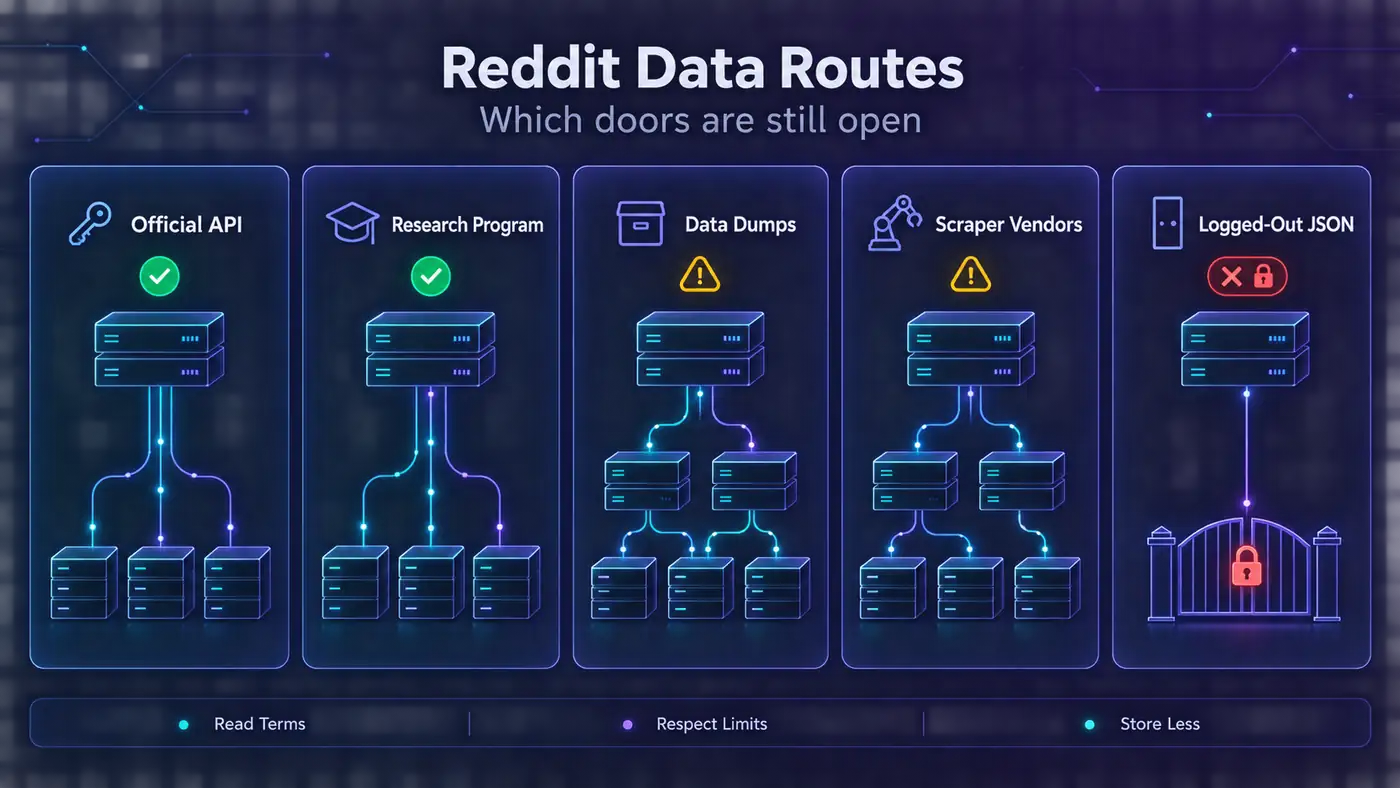
| Route | Best for | Cost | The catch |
|---|---|---|---|
| Official API | Approved non-commercial apps and bots | Free within the rate limit | No new requests after October 31, 2026; public access ends March 2027 |
| Reddit for Researchers | Academics at accredited universities | Free | Ethics approval, a six-month delay and no commercial use |
| Commercial license | Companies building products | Negotiated contract | No public price list |
| Data dumps | Historical analysis | Free, plus storage | Third-party archive; Reddit’s policy forbids research use outside its program |
| Scraping vendors | One-off public datasets | About $1.50 per 1,000 records | Reddit’s terms prohibit scraping without its consent |
Our take: if you’re an academic, use the research program. If you’re building a product, talk to Reddit or a licensed provider. Everyone else should apply for API access now, while the window is open.
Route 1: The Official API with PRAW
PRAW, the Python Reddit API Wrapper, is still the easiest way to work with Reddit’s official API. Version 8.0.3 shipped in August 2026 and needs Python 3.10 or newer. What changed is how you get credentials.
A quick note on testing: we don’t have an approved app, so we couldn’t run these scripts against live Reddit. We checked every snippet against PRAW 8.0.3 with a mocked API, which catches wrong method names and fields.
1Request Access Before October 31, 2026
Since late 2025, Reddit’s Responsible Builder Policy has been blunt: “You must request access and get explicit approval before accessing any Reddit data through our API.” Creating an app on the old preferences page no longer hands you working keys.
Apply through Reddit’s developer support form and describe one use case honestly. The policy bans “submitting multiple requests for the same use case,” so a rejection can’t be fixed by applying again under another account.
Deadlines: new public API requests close on October 31, 2026. Approved apps must register by January 12, 2027, and public access ends in March 2027.
Apps created before the policy reportedly keep working, but they need registering too. After March 2027, tools such as AI assistants and social listening products will need commercial deals, TechCrunch reports.
2Install PRAW and Authenticate
Install the library, then keep your credentials in environment variables rather than in your code:
pip install praw
import os
import praw

reddit = praw.Reddit(
    client_id=os.environ["REDDIT_CLIENT_ID"],
    client_secret=os.environ["REDDIT_CLIENT_SECRET"],
    user_agent="python:com.example.subreddit-research:v1.0 (by u/your_username)",
)
print(reddit.read_only)  # True: public data needs no Reddit password
That User-Agent format comes from Reddit’s API wiki: platform, app ID, version and your username. Generic agents such as “Python/urllib” are “drastically limited,” and the wiki adds, in capitals, “NEVER lie about your User-Agent.”
New to Python scraping in general? Our Python web scraping guide covers the basics.
3Pull a Subreddit’s Top Posts into a CSV
This script saves a month of top posts from r/webscraping:
import csv

rows = []
for post in reddit.subreddit("webscraping").top(time_filter="month", limit=100):
    rows.append({
        "id": post.id,
        "title": post.title,
        "score": post.score,
        "upvote_ratio": post.upvote_ratio,
        "num_comments": post.num_comments,
        "created_utc": int(post.created_utc),
        "url": "https://www.reddit.com" + post.permalink,
    })

with open("webscraping_top_month.csv", "w", newline="", encoding="utf-8") as f:
    writer = csv.DictWriter(f, fieldnames=list(rows[0]))
    writer.writeheader()
    writer.writerows(rows)
print(f"Saved {len(rows)} posts")
Each post object carries more fields than this, including the body text, flair and NSFW flag. We left author names out on purpose. You rarely need them, and they count as personal data under laws such as the GDPR.
4Get the Full Comment Tree
Comments arrive as a tree, with “load more” stubs wherever Reddit collapsed a branch. PRAW’s replace_more() deals with them:
submission = reddit.submission(id="1abc234")
submission.comments.replace_more(limit=0)  # drop the "load more comments" stubs

for comment in submission.comments.list():
    print(comment.score, comment.body[:80].replace("\n", " "))
limit=0 drops the stubs, which is fast. limit=None expands every branch, but each stub costs one more API request, so big threads eat your rate limit quickly.
5Search and Stay Under the Rate Limit
results = reddit.subreddit("all").search(
    '"residential proxies"', sort="new", time_filter="year", limit=50
)
for post in results:
    print(post.subreddit.display_name, post.score, post.title)

print(reddit.auth.limits)  # requests used and remaining in this window
The free limit is 100 queries per minute per OAuth client ID, averaged over 10 minutes, according to Reddit’s Data API wiki. PRAW reads the rate-limit headers and pauses for you.
Don’t try to beat the limit with extra keys or accounts. The policy says you “must not circumvent or exceed access limits,” and it’s the quickest way to lose access.
The 1,000-item ceiling: most listings, such as a subreddit’s new or top posts, stop at 1,000 items, returned 100 at a time. PRAW’s docs call it an “upstream limitation.” For deeper history, use the research program or the dumps below.
Route 2: Reddit for Researchers
If you’re an academic, this is the route Reddit wants you on, and it’s free. The Reddit for Researchers program offers public content through Google’s BigQuery Analytics Hub.
You get five years of historical data with a six-month delay, updated monthly. In return, you need an accredited university affiliation, a sponsoring principal investigator and approval from an ethics board such as an IRB. Commercial use isn’t allowed.
Access lasts up to a year, and deleted, NSFW, private and quarantined content is excluded. The policy is strict about alternatives: research using Reddit data “collected outside of the RFR Program is in violation of this policy.”
Route 3: Historical Dumps from Arctic Shift
For history, the community archive Arctic Shift publishes monthly Reddit dumps as compressed files. When we checked on October 9, 2026, its download page listed releases through August 2026, plus a full 2005 to 2025 bundle of about 3.8 TB.
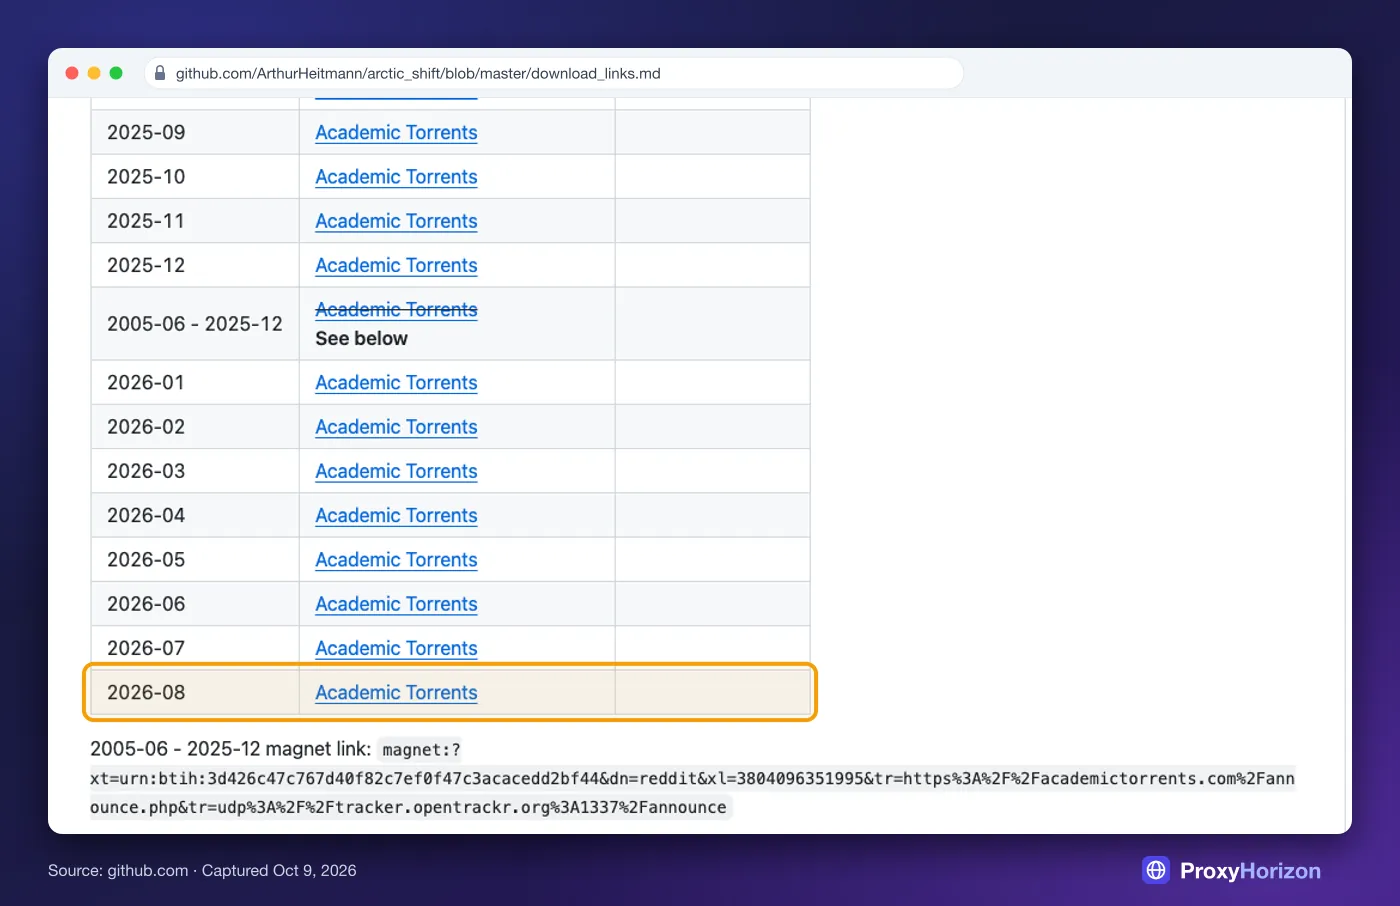
The files are zstandard-compressed JSON, with one post or comment per line. This reader streams a monthly file without unpacking it to disk:
import io
import json
import zstandard  # pip install zstandard

def read_dump(path):
    with open(path, "rb") as fh:
        decompressor = zstandard.ZstdDecompressor(max_window_size=2**31)
        reader = decompressor.stream_reader(fh)
        for line in io.TextIOWrapper(reader, encoding="utf-8"):
            yield json.loads(line)

for post in read_dump("submissions_2026-08.zst"):
    if post.get("subreddit") == "webscraping":
        print(post["created_utc"], post["score"], post["title"])
Check before you build on it: Arctic Shift is a third-party archive, not a Reddit product. The dumps include posts that users later deleted, and Reddit’s policy treats research outside its own program as a violation.
Scores also keep changing for about 36 hours after a post goes up, so the newest data can be slightly off. Pushshift, the tool most old guides recommend, now serves only moderators.
Route 4: Licensed Data and Scraping Vendors
Businesses face the strictest rules. Reddit defines commercial use as any use “by a business or on behalf of a business,” and says it needs “our permission, and we’ll require a contract.” Google and OpenAI took that route with licensing deals in 2024.
Reddit publishes no price list. The only public figure is its 2023 rate of $0.24 per 1,000 API calls for heavy users, and enterprise deals are negotiated.
Scraping vendors sell Reddit data without that contract. Bright Data’s Reddit scraper API lists $1.50 per 1,000 records on pay-as-you-go, with 5,000 free records a month, and its ready-made Reddit datasets start at a $250 order. Reddit scrapers on Apify charge roughly $1.19 to $4 per 1,000 results.
Warning: a vendor carries the scraping work, not your legal exposure. Reddit’s User Agreement says scraping “without Reddit’s prior written consent is prohibited,” and Reddit has sued data companies over exactly this. If you’re building a product on Reddit data, get legal advice first.
Comparing vendors anyway? Our roundups of Apify actors for social media and web scraping APIs cover the main options.
Why Proxies Won’t Fix a Reddit 403
We review proxies for a living, so here’s the uncomfortable truth: for Reddit, more IPs aren’t the answer anymore.
Reddit’s own rules close that door. Requests from datacenter IP ranges need “a valid OAuth token or be logged in,” per its developer help page, and those ranges are easy to identify, as our guide to how websites detect proxy traffic shows.
Rotating residential proxies to slip past a block is circumvention by design, which the policy forbids.
The legal risk now sits right there. In October 2025, Reddit sued SerpApi, Oxylabs, AWMProxy and Perplexity, alleging they pulled Reddit content from Google search results by evading Google’s anti-bot system. Oxylabs, one of the largest proxy providers, says it provides infrastructure for compliant access to public information.
On July 31, 2026, the judge let Reddit’s anti-circumvention claims under the DMCA go forward against SerpApi and Perplexity, treating Google’s SearchGuard as a technological protection measure. Reddit is also suing Anthropic in a separate case filed in June 2025, which is now in discovery.
Even scraping APIs have stepped back. Firecrawl, for example, has blocked most reddit.com pages since at least 2025. Our Firecrawl use cases guide covers what it does handle.
Our take: proxies are still the right tool for sites that allow automated access, and our proxy directory compares providers for that work. Reddit isn’t one of those sites anymore. This isn’t legal advice, so talk to a lawyer before you build anything commercial on Reddit data.
What Reddit Data Costs by Route
Here’s what 100,000 posts or comments would cost on each route, based on prices published in October 2026:
| Route | Cost for 100,000 items | Notes |
|---|---|---|
| Official API, non-commercial | Free | Approved apps only, 100 queries a minute |
| Official API, commercial | Contract | No public rate card |
| Reddit for Researchers | Free | Academics only |
| Arctic Shift dumps | Free | The full archive is about 3.8 TB |
| Bright Data scraper API | About $150 | 5,000 free records a month |
| Bright Data dataset | From $250 | Minimum order |
| Apify Reddit scrapers | About $119 to $400 | Price depends on the actor |
The API looks generous on paper. At 100 queries a minute and up to 100 items per request, an approved app could read 10,000 items a minute.
In practice, the 1,000-item listing cap and comment trees slow you down, since every “load more” stub costs another request. Budget hours, not minutes, for big threads.
Mistakes That Get Reddit Projects Shut Down
1Following a Tutorial Written Before 2026
Most top-ranking guides still teach the .json trick, Old Reddit HTML and instant keys from the app settings page. All three stopped working for new users between late 2025 and mid-2026. Check a tutorial’s date before you copy its code.
2Faking Your User-Agent
A browser User-Agent won’t get you past the .json block, and Reddit’s wiki says to “NEVER lie” about it. A descriptive agent with your username is how Reddit tells a well-behaved tool from a scraper.
3Splitting One Project Across Several Keys
Five keys don’t give you five times the rate limit. They give Reddit a reason to revoke all of them, because the policy bans multiple accounts or requests for the same use case.
4Keeping Deleted Posts and User Data
Reddit’s wiki strongly recommends deleting stored user data and content within 48 hours, and its developer terms require you to remove content that’s been deleted on Reddit. Store IDs and aggregates, and refresh rather than hoard.
5Training a Model Without a Deal
Reddit’s developer terms bar using its data “to train large language, artificial intelligence, or other algorithmic models” without permission. That applies even to data you collected legitimately through the API.
Frequently Asked Questions
The Bottom Line
Reddit data hasn’t disappeared. The free-for-all has.
If you build tools, apply for API access before October 31 and register your app by January 12. If you’re an academic, apply to Reddit for Researchers. If you’re a business, budget for a license or a vendor, and get legal advice before you pick the vendor route.
Whatever you choose, don’t build anything new on .json, RSS or logged-out Old Reddit. For sites that still welcome scrapers, our guide to web scraping is the place to start.